|
I am a PhD candidate in the Computer Vision Group at the University of Bonn, supervised by Prof. Dr. Juergen Gall, and currently working in the domain of Multimodal Video Understanding. Previously, I completed my master's degree at the University of Hanover, supervised by Prof. Dr. Bodo Rosenhahn. I hold an undergraduate degree in Electrical Engineering, with a minor in computer science, from the South China University of Technology. My current research focuses on multimodal video understanding, long-term action anticipation and object re-indentification. Previously, I also worked on unsupervised domain adaptation, and applications of computer vision to plant phenotyping. Email / Google Scholar / Github / Linkedin |
|
|
|
|
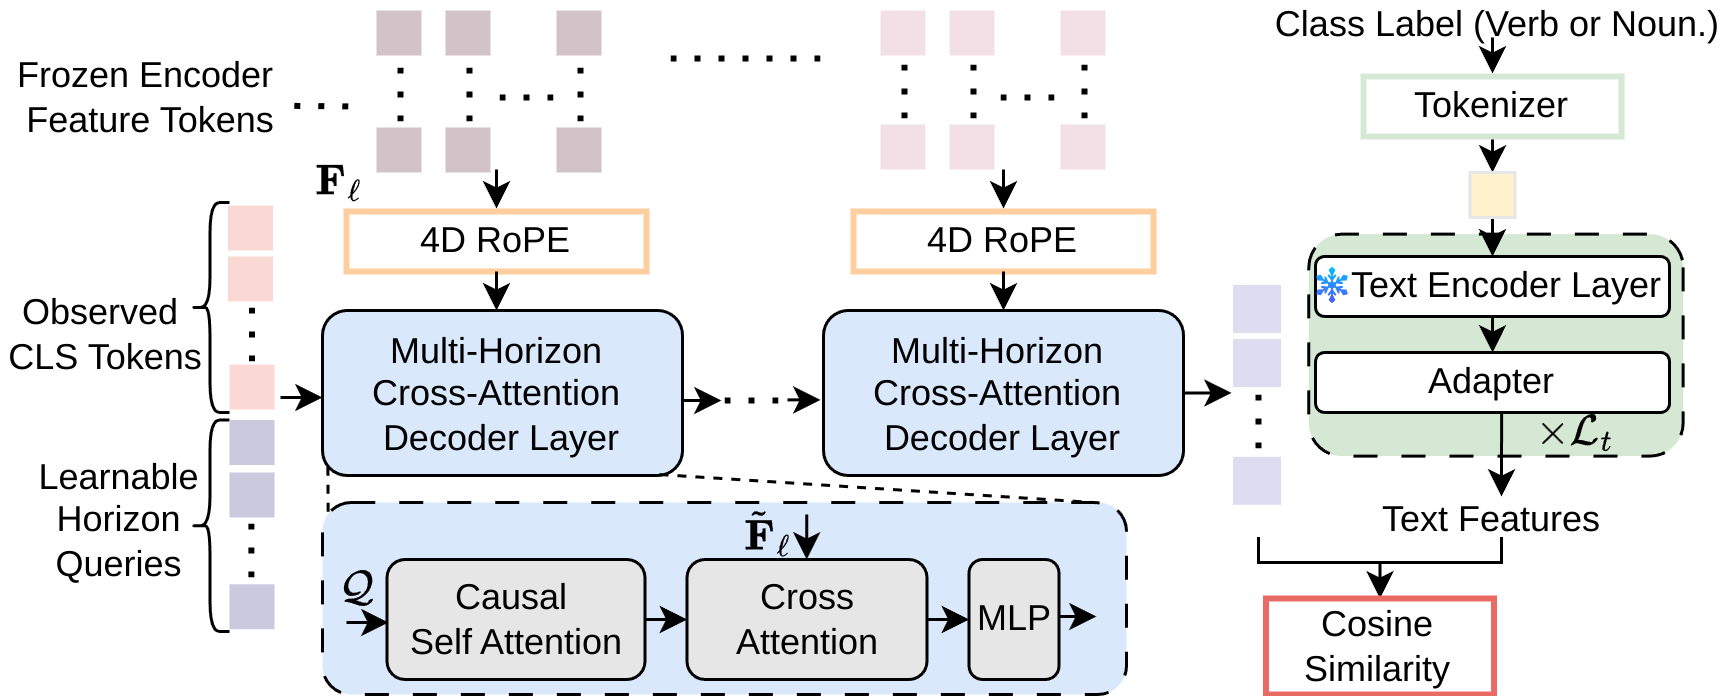
Syed Talal Wasim*, Jinhui Yi*, Hamid Suleman, Ahmad Javed, Yanan Luo, Muzammal Naseer, Juergen Gall ECCV 2026 Paper Introduces the first open-vocabulary evaluation setting for action anticipation, testing models on entirely unseen action vocabularies across egocentric datasets. |
|
|
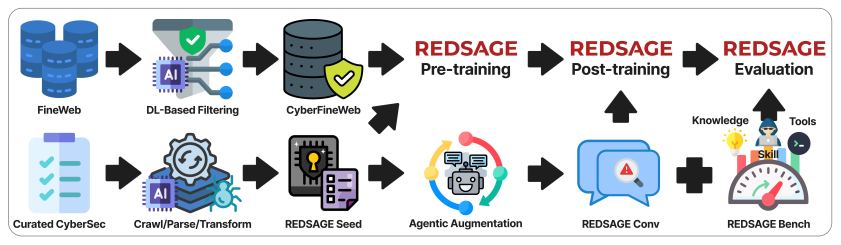
Naufal Suryanto, Muzammal Naseer, Pengfei Li,, Syed Talal Wasim, Jinhui Yi, Juergen Gall, Paolo Ceravolo, Ernesto Damiani ICLR 2026 Paper / Code / Data / Project Page An open, locally deployable 8B cybersecurity LLM trained on a large curated corpus and agentic dialogue data, outperforming baselines on both security-specific and general benchmarks. |
|
|
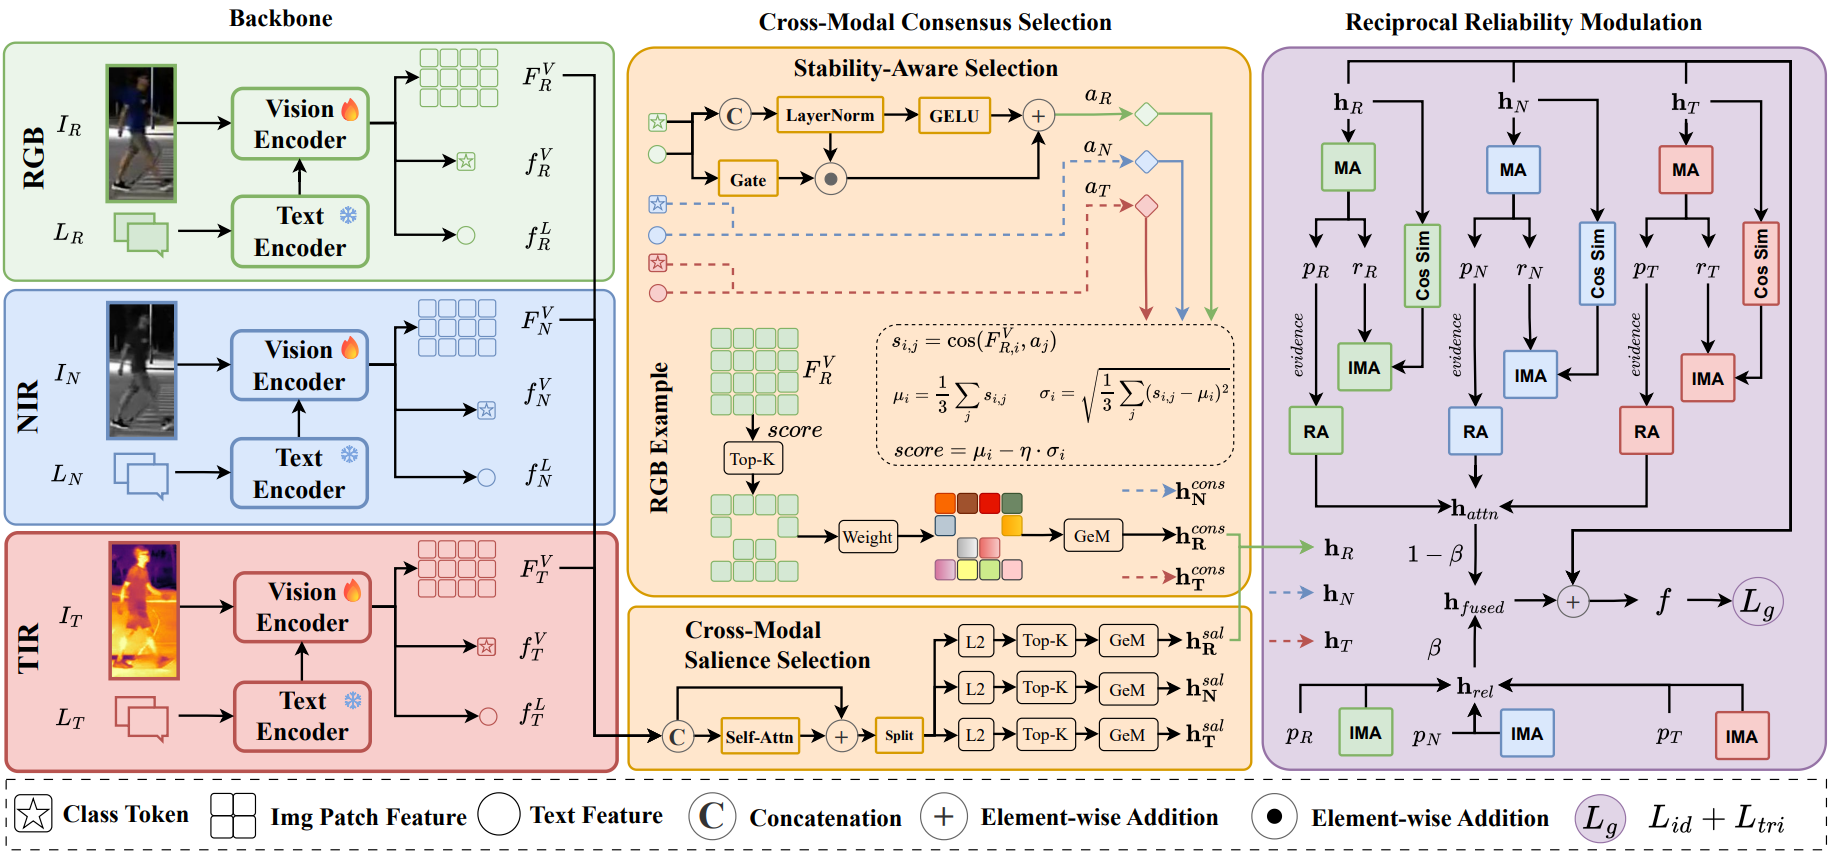
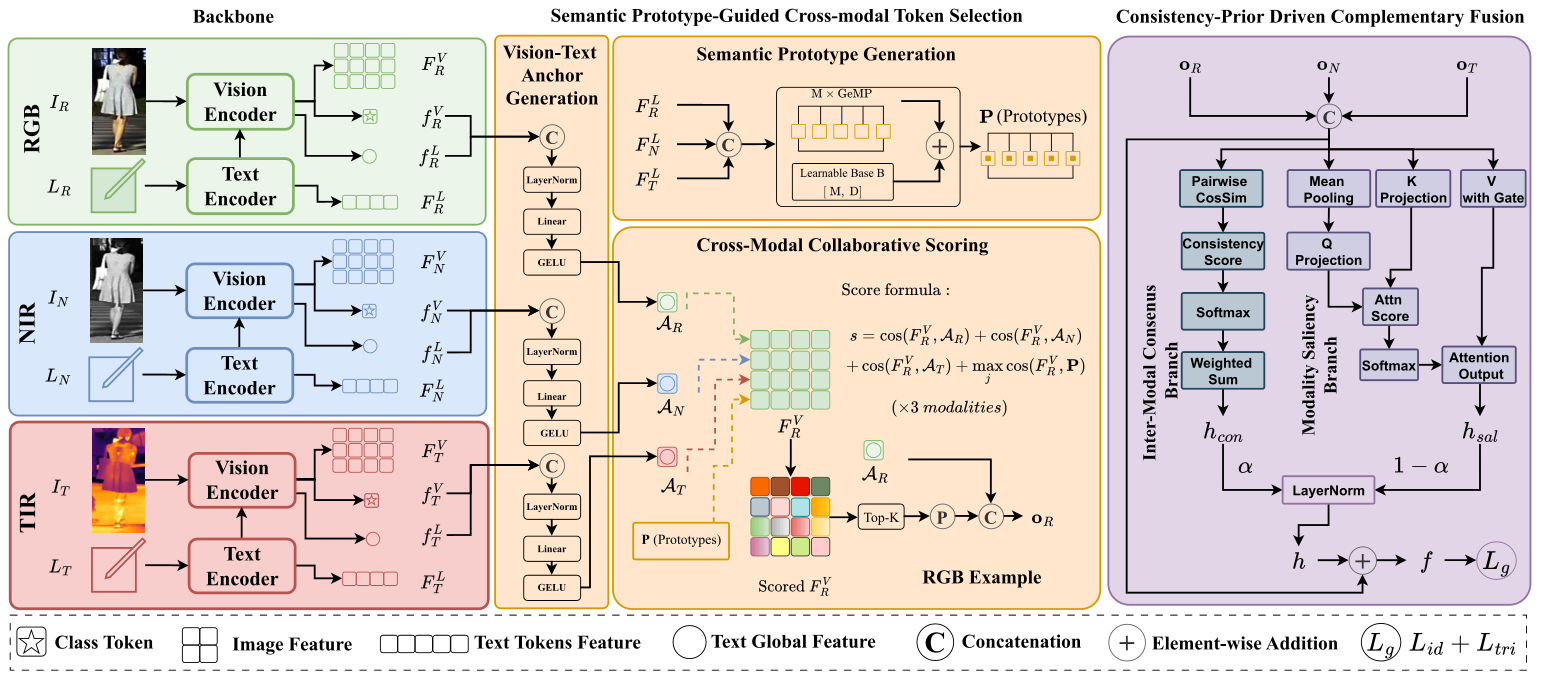
Xingan Ma, Jinhui Yi, Juergen Gall ICIP 2026 Paper Proposes consensus-based token selection and reliability-aware fusion to suppress modality-specific noise in multi-modal object re-identification. |
|
|
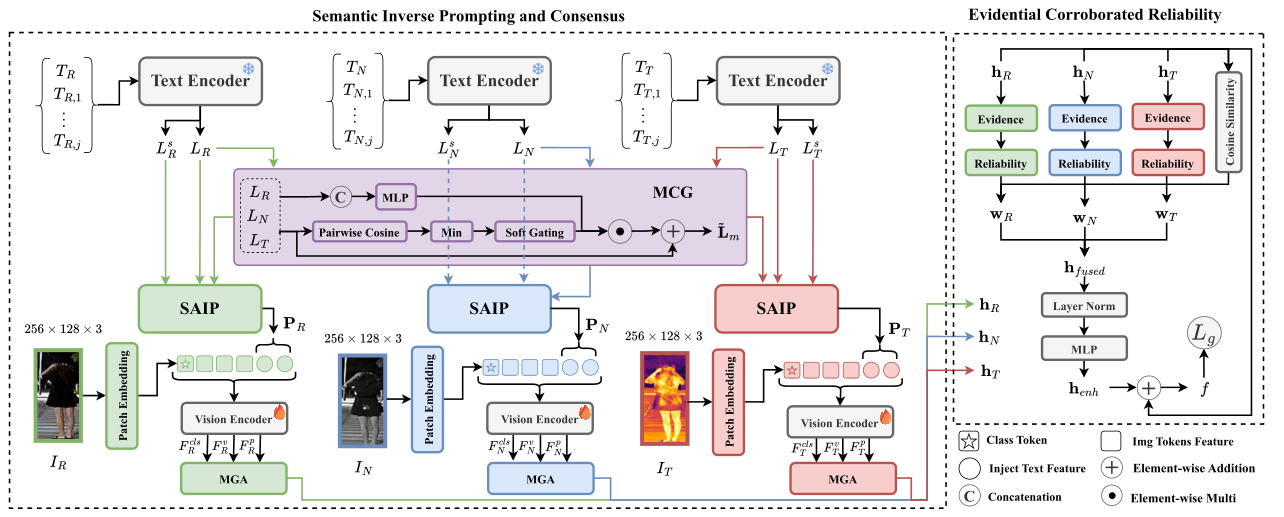
Xingan Ma, Yuhao Wang, Jinhui Yi, Juergen Gall IJCNN 2026 Uses semantic inverse prompting and evidential reliability estimation to denoise and fuse multi-modal re-identification features. |
|
|
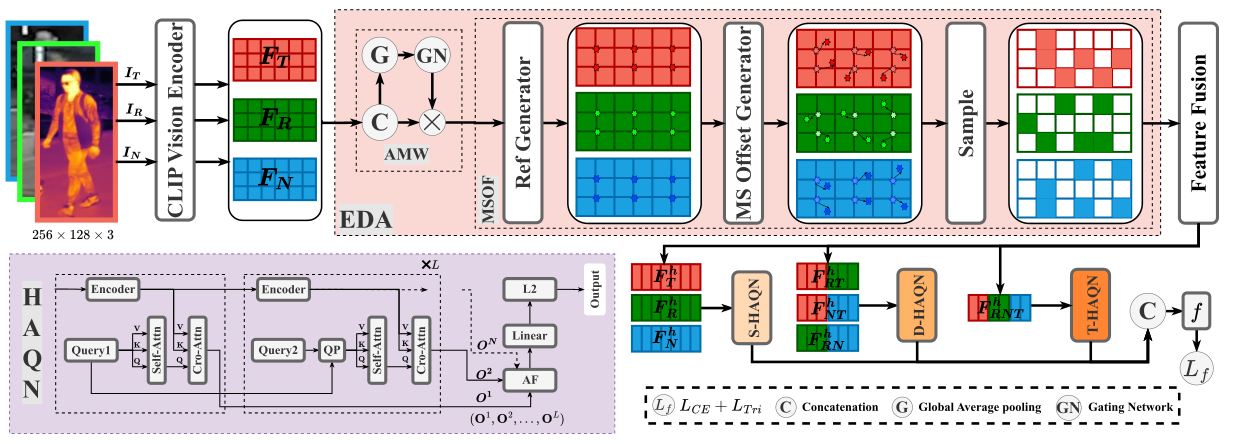
Xingan Ma, Yuhao Wang, Jinhui Yi, Juergen Gall IJCNN 2026 Combines adaptive deformable attention with hierarchical query learning to handle varying modality importance and spatial misalignment in multi-modal re-identification. |
|
|
Xingan Ma, Yuhao Wang, Jinhui Yi, Ruijuan Zhang, Pingping Zhang, Juergen Gall ICME 2026 Uses text-derived semantic prototypes to purify visual tokens and a consistency-prior fusion module for robust multi-modal re-identification. |
|
|
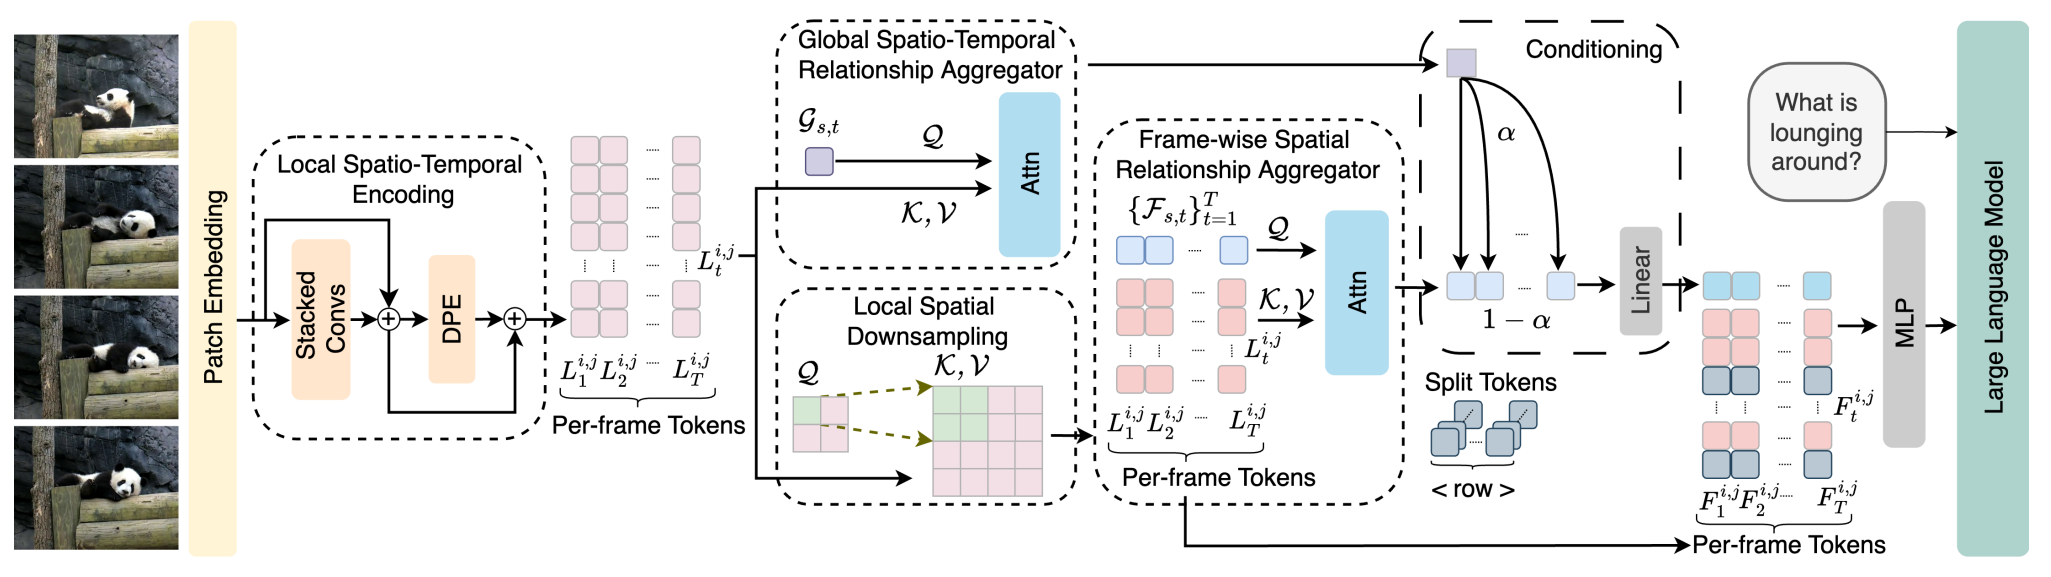
Jinhui Yi*, Syed Talal Wasim*, Yanan Luo*, Muzammal Naseer, Juergen Gall CVPR 2025 Paper / Code / Project Page The first encoder-free video-language model, replacing heavy visual encoders with a lightweight alignment block for a large parameter and speed savings. |
|
|
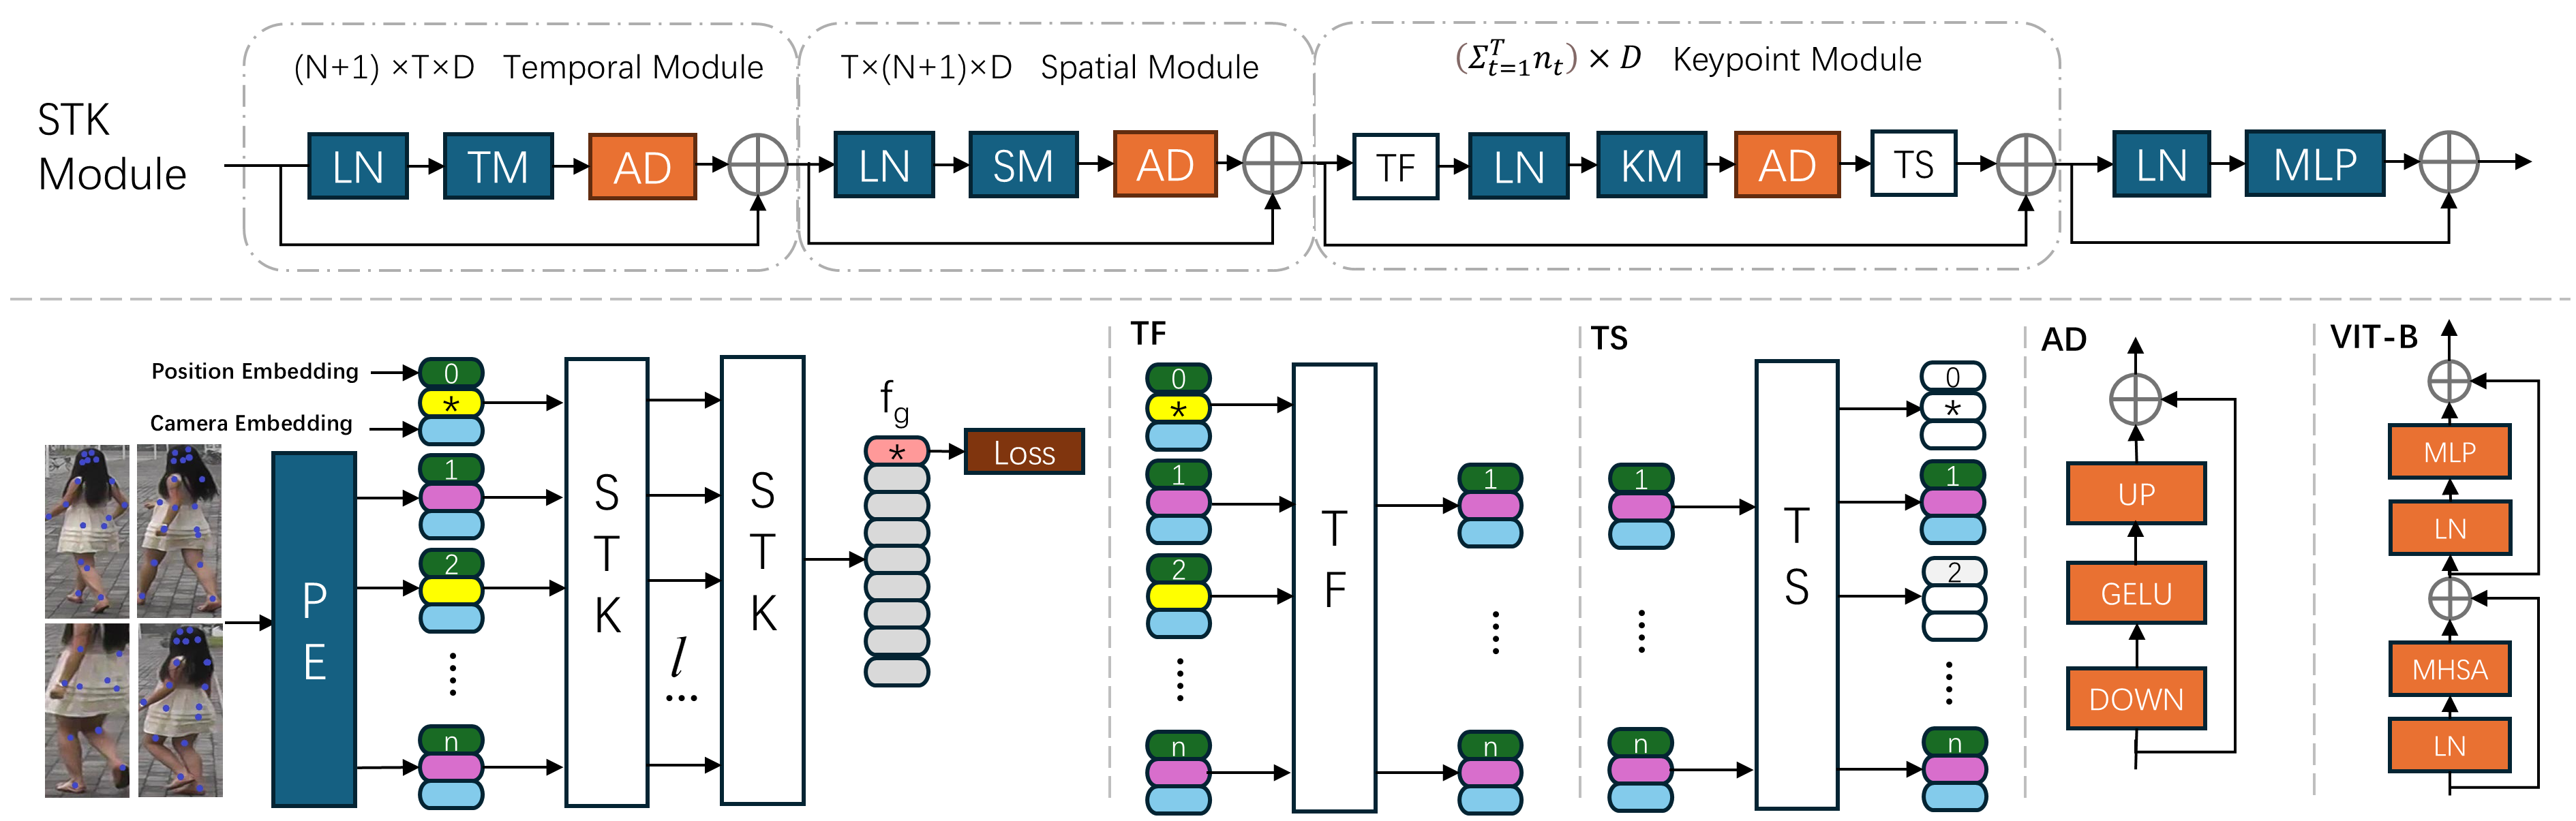
Xingan Ma, Jinhui Yi, Juergen Gall ICASSP 2025 Paper A parameter-efficient transformer that aggregates spatial, temporal, and keypoint cues with lightweight adapters for video-based person re-identification. |
|
|
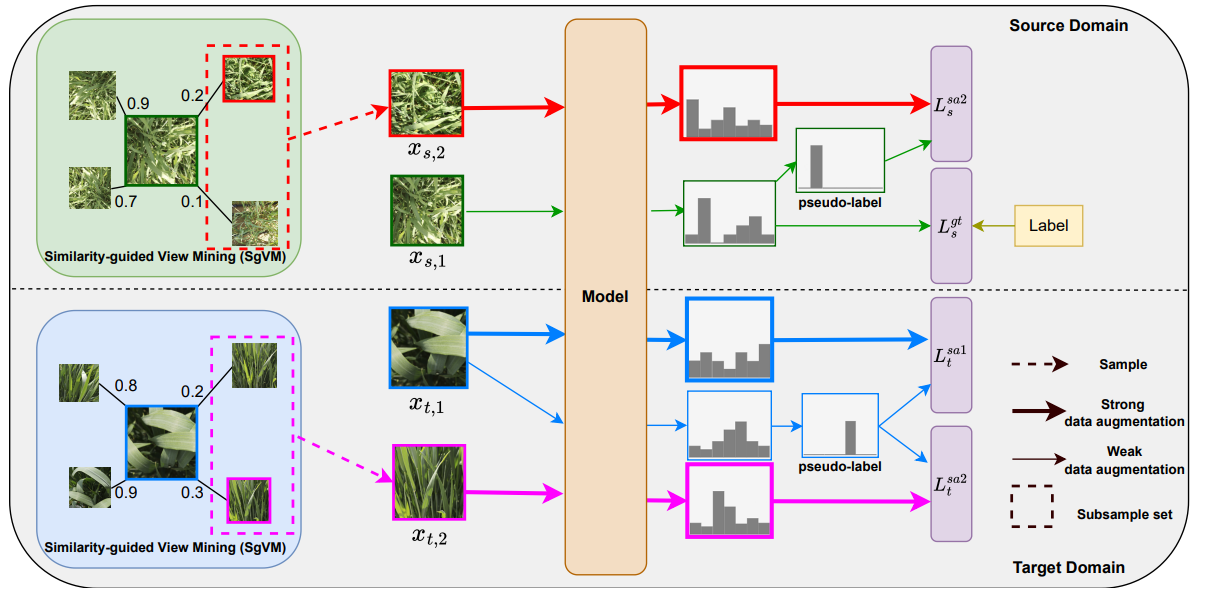
Jinhui Yi*, Yanan Luo*, Marion Deichmann, Gabriel Schaaf, Juergen Gall BMVC 2024 Paper / Code & Data The first method to exploit multiple camera views in both the source and target domains for unsupervised domain adaptation of plant nutrient-deficiency detection. |
|
|
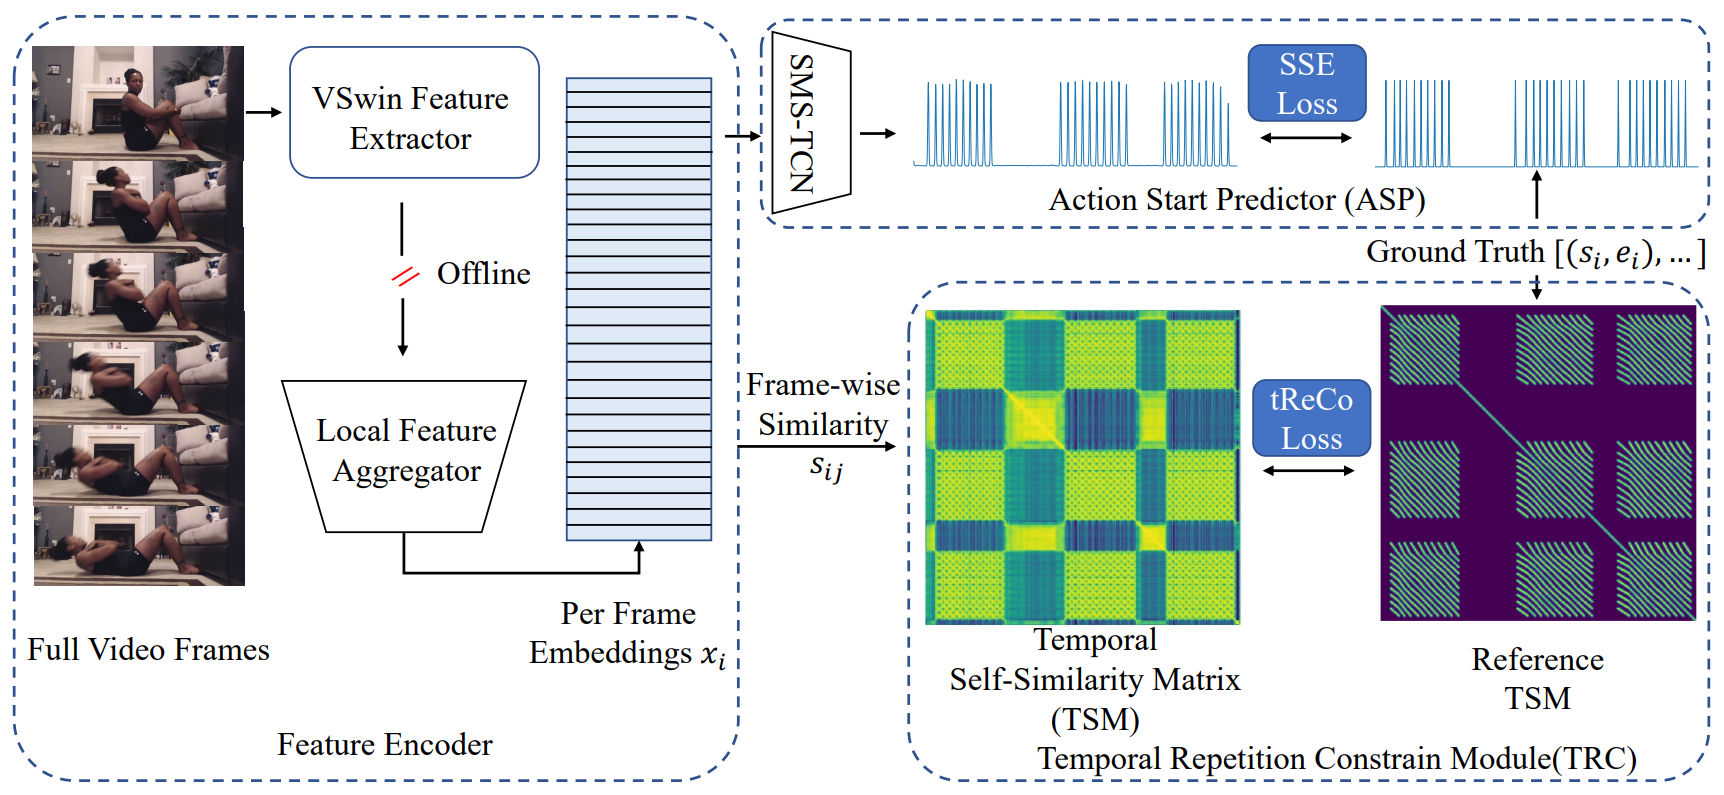
Yanan Luo*, Jinhui Yi*, Yazan Abu Farha, Moritz Wolter, Juergen Gall ICIP 2024 Paper / Code & Data Replaces the intermediate self-similarity matrix with full-resolution frame embeddings and a reference-based loss for more accurate repetitive action counting. |
|
|
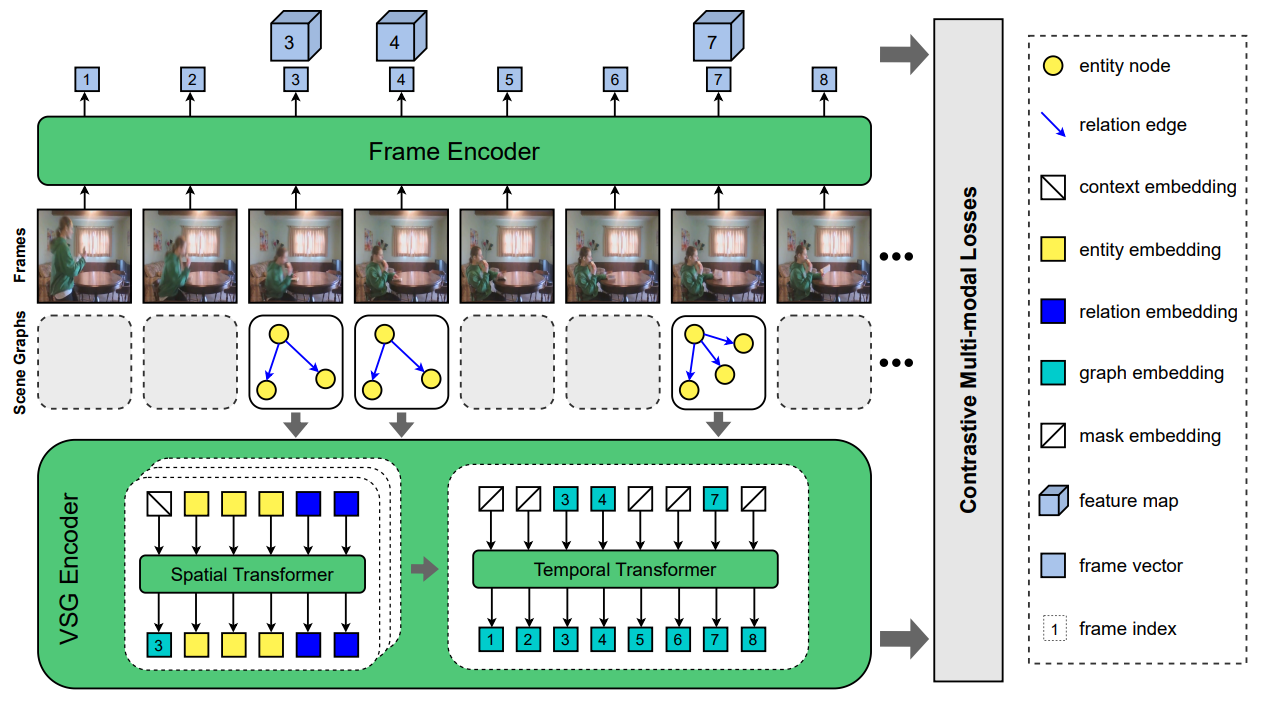
Yuren Cong, Jinhui Yi, Bodo Rosenhahn, Michael Ying Yang CVPRW 2023 Paper / Code Uses semantic video scene graphs, encoded and predicted frame-by-frame, to guide temporally-aware video synthesis. |
|
|
Shijie Li, Yanying Zhou, Jinhui Yi, Juergen Gall ICCV 2021 A compact graph-based network combining dilated temporal convolutions and graph convolutions for accurate, low-latency trajectory forecasting. |
|
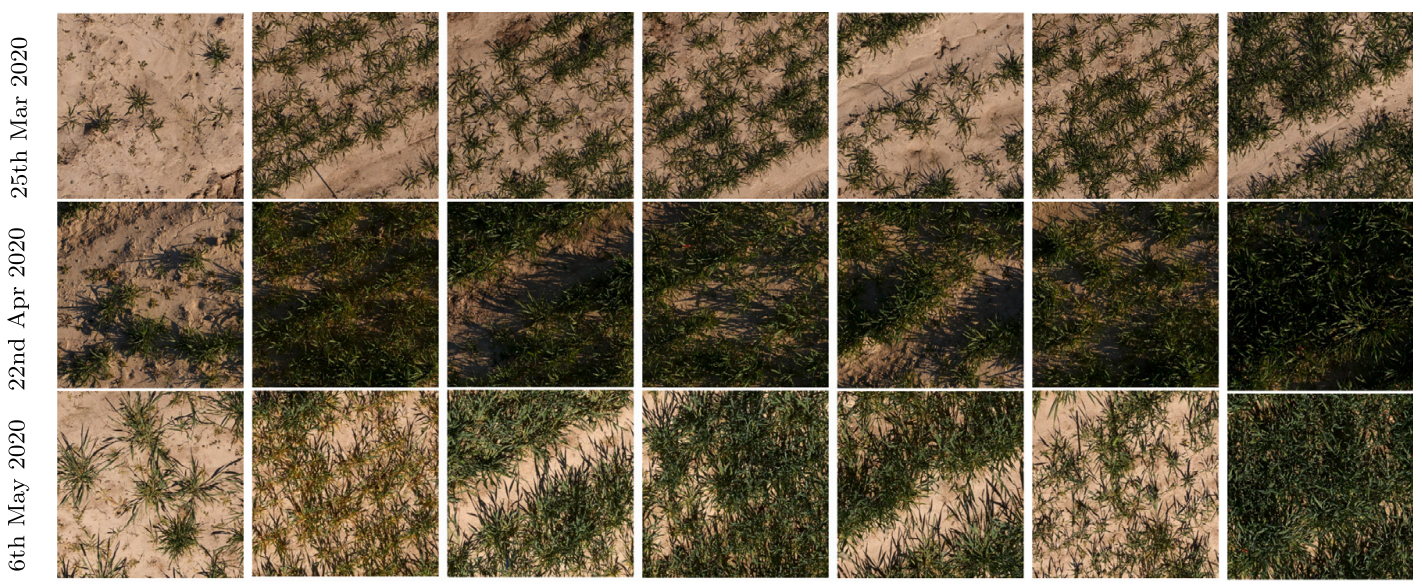
Jinhui Yi, Gina Lopez, Sofia Hadir, Jan Weyler, Lasse Klingbeil, Marion Deichmann, Juergen Gall, Sabine J Seidel Computers and Electronics in Agriculture (COMPAG), 2025 Paper / Code / Data Benchmarked eight CNN- and transformer-based models on drone imagery of winter wheat and rye to detect specific nutrient-deficiency treatments, reaching 75-81% average accuracy within a season. |
|
|
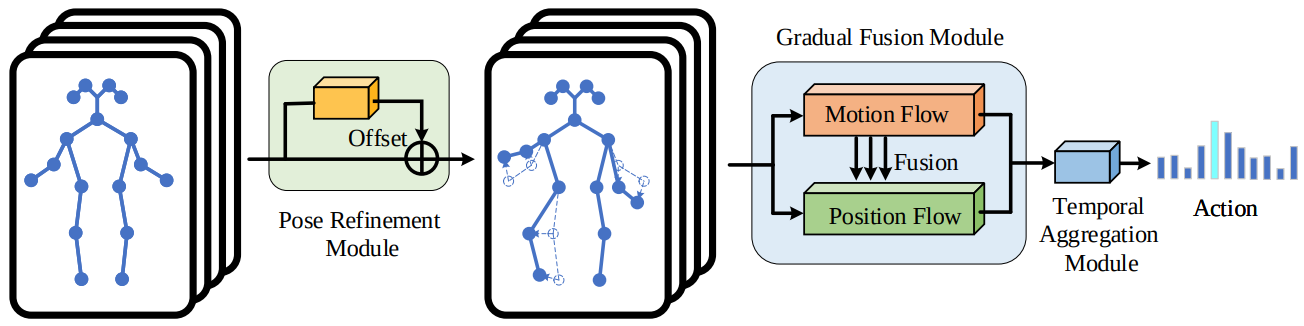
Shijie Li*, Jinhui Yi*, Yazan Abu Farha, Juergen Gall IEEE Robotics and Automation Letters (RA-L), 2021 Paper / Code A lightweight graph convolutional network that refines noisy skeleton poses before recognition, cutting parameters and computation by roughly 90% with comparable accuracy. |
|
|
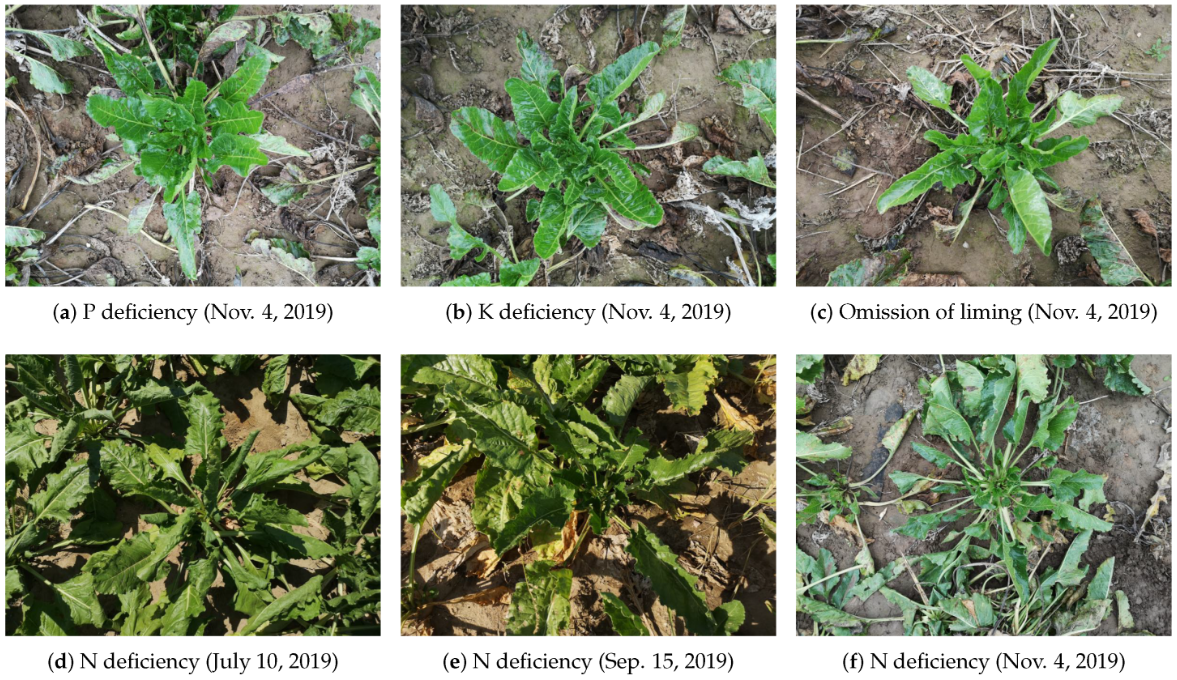
Jinhui Yi, Lukas Krusenbaum, Paula Unger, Hubert Hüging, Sabine J Seidel, Gabriel Schaaf, Juergen Gall Sensors, 2020 Paper / Code / Data Introduced the 5,648-image DND-SB dataset and benchmarked five CNNs for recognizing nutrient-deficiency symptoms in sugar beet RGB images. |
|
|